Adversarial robustness and safe AI systems
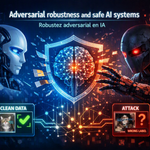
Adversarial robustness in AI systems refers to the ability of these systems to withstand and function correctly even when faced with adversarial inputs—inputs that are intentionally designed to cause the system to make errors. This is a critical area of research in AI safety, as adversarial attacks can exploit vulnerabilities in AI models, leading to incorrect or harmful outputs.
The document titled «Mapping Human Anti-collusion Mechanisms to Multi-agent AI Systems» by Jamiu Idowu, Ahmed Almasoud, and Ayman Alfahid discusses the challenges of ensuring safe and reliable behavior in multi-agent AI systems. Although it does not specifically mention adversarial robustness, it highlights the importance of developing mechanisms to prevent collusion among AI agents, which can be seen as a form of adversarial behavior. The paper proposes mapping human anti-collusion mechanisms, such as sanctions and monitoring, to AI systems to mitigate such risks. This approach aligns with the broader goal of enhancing AI safety by ensuring that AI systems behave as intended, even in the presence of adversarial or collusive strategies.
The document «Faith in AI can narrow the futures individuals consider» by Aoi Naito and Hirokazu Shirado explores how AI predictions can influence human decision-making. While it does not directly address adversarial robustness, it touches on the theme of AI safety by examining how the perceived authority of AI predictions can shape human behavior, potentially leading to suboptimal decisions. This highlights the need for robust AI systems that not only make accurate predictions but also consider the broader impact of their interactions with humans.
The «Foundations of GenIR» document by Qingyao Ai, Jingtao Zhan, and Yiqun Liu discusses the impact of generative AI models on information access systems. It emphasizes the importance of high-quality, human-like responses and the potential for generative AI to enhance information synthesis and generation. While adversarial robustness is not explicitly mentioned, the document underscores the need for AI systems to provide reliable and accurate information, which is a key aspect of AI safety.
In summary, while the provided documents do not specifically address Zico Kolter’s work on adversarial robustness, they highlight related themes in AI safety, such as preventing collusion in multi-agent systems, understanding the influence of AI predictions on human behavior, and ensuring the reliability of generative AI models. These themes are integral to developing safe AI systems that can withstand adversarial challenges and function effectively in complex environments.
For further reading on adversarial robustness and safe AI systems, you may explore Zico Kolter’s publications on arXiv or other academic platforms. Unfortunately, specific links to his work are not provided in the context above.The topic of adversarial robustness and certified defenses in the context of machine learning, particularly with respect to large language models (LLMs) and security, is a critical area of research. This discussion will draw upon the context provided by the documents, focusing on the contributions of Zico Kolter and others in the field of adversarial robustness, and how these concepts apply to the security of LLMs.
Adversarial Robustness and Certified Defenses
Adversarial robustness refers to the ability of machine learning models to withstand adversarial attacks—deliberate manipulations of input data designed to deceive the model into making incorrect predictions. These attacks pose significant challenges, especially in safety-critical applications such as autonomous driving, financial fraud detection, and cybersecurity.
Zico Kolter and his colleagues have made significant contributions to this field, particularly through the development of techniques like randomized smoothing. Randomized smoothing is a method that transforms any classifier into one that is certifiably robust against adversarial perturbations under the ( \ell_2 ) norm. This technique involves adding Gaussian noise to inputs and has been shown to provide tight robustness guarantees, making it a promising direction for future research into adversarially robust classification (Cohen et al., 2019).
Link to the document: Certified Adversarial Robustness via Randomized Smoothing
Application to Large Language Models (LLMs)
Large language models, such as GPT-3 and its successors, have revolutionized natural language processing by achieving state-of-the-art performance on a wide range of tasks. However, their deployment in real-world applications raises security concerns, particularly regarding their susceptibility to adversarial attacks.
- Adversarial Attacks on LLMs:
- Adversarial attacks on LLMs can involve subtle manipulations of input text that lead to incorrect or harmful outputs. For instance, inserting typos or altering sentence structures can mislead text classification or dialogue systems (Xu et al., 2019).
- Certified Defenses for LLMs:
- Applying techniques like randomized smoothing to LLMs could enhance their robustness against such attacks. By ensuring that the model’s predictions remain consistent under small perturbations, these methods can provide a level of certified security that is crucial for applications involving sensitive data or decision-making processes.
- Challenges and Future Directions:
- One of the main challenges in applying certified defenses to LLMs is the scalability of these methods. LLMs are typically large and complex, making it difficult to apply existing robustness certification techniques directly. Research is needed to adapt and scale these methods to handle the unique characteristics of LLMs.
Security Implications
The security of LLMs is a growing concern as they are increasingly integrated into systems that handle sensitive information. Ensuring that these models are robust to adversarial attacks is essential for maintaining trust and reliability in AI systems.
- Impact on Cybersecurity:
- In cybersecurity, adversarial attacks on models used for malware detection or intrusion detection can have severe consequences. Techniques like adversarial deep ensemble learning, which combines multiple models to enhance robustness, are being explored to counteract these threats (Li & Li, 2020).
- Regulatory and Ethical Considerations:
- As LLMs are deployed in more critical applications, there is a need for regulatory frameworks that mandate robustness and security standards. Ethical considerations also come into play, as adversarial attacks can lead to biased or harmful outputs, affecting user trust and safety.
Link to the document: Adversarial Deep Ensemble: Evasion Attacks and Defenses for Malware Detection
Conclusion
The work of Zico Kolter and others in the field of adversarial robustness provides valuable insights into developing certified defenses for machine learning models. As LLMs continue to evolve and find applications in various domains, ensuring their security against adversarial attacks becomes increasingly important. Techniques like randomized smoothing offer promising avenues for enhancing the robustness of these models, but further research is needed to address the unique challenges posed by LLMs. By advancing our understanding of adversarial robustness and certified defenses, we can build more secure and reliable AI systems that can be trusted in critical applications.Randomized smoothing has emerged as a powerful technique for certifying the robustness of classifiers against adversarial perturbations. This method, which has been explored in various studies, including those by Cohen et al. (2019) and Jeong and Shin (2021), transforms a base classifier into a smoothed classifier that is robust to adversarial attacks. The core idea is to average the predictions of a classifier over Gaussian noise, thereby converting worst-case adversarial robustness into average-case Gaussian robustness. This approach has been shown to provide strong, model-agnostic robustness certificates, making it a promising direction for future research into adversarially robust classification.
The concept of randomized smoothing was further developed by Cohen, Rosenfeld, and Kolter in their 2019 paper, «Certified Adversarial Robustness via Randomized Smoothing» (arXiv:1902.02918). They demonstrated how any classifier that performs well under Gaussian noise can be transformed into a new classifier that is certifiably robust to adversarial perturbations under the (\ell_2) norm. This transformation is achieved through a process called «randomized smoothing,» which involves adding Gaussian noise to the input data and averaging the classifier’s predictions over this noise. The authors provided a tight robustness guarantee for smoothing with Gaussian noise and applied this technique to obtain an ImageNet classifier with a certified top-1 accuracy of 49% under adversarial perturbations with an (\ell_2) norm less than 0.5. This result was significant because no other certified defense had been shown feasible on ImageNet except for smoothing.
The technique of randomized smoothing has been extended to handle more complex scenarios, such as multimodal inputs, where decisions depend on cross-modal semantics. Delattre et al. (2026) introduced a unified randomized smoothing framework for mixed discrete-continuous inputs, addressing the limitations of existing guarantees that are confined to single modalities. Their approach, detailed in «Certified Robustness under Heterogeneous Perturbations via Hybrid Randomized Smoothing» (arXiv:2605.12876), provides a closed-form, one-dimensional certificate that generalizes both Gaussian (image-only) and discrete (text-only) randomized smoothing. This framework is particularly relevant for multimodal models, where adversaries can jointly perturb heterogeneous inputs, rendering unimodal certificates insufficient.
Another significant contribution to the field is the work by Jeong and Shin (2021), who explored the trade-off between accuracy and certified robustness of smoothed classifiers. In their paper, «Consistency Regularization for Certified Robustness of Smoothed Classifiers» (arXiv:2006.04062), they proposed a method to control this trade-off by regularizing the prediction consistency over noise. This approach allows for the design of a robust training objective without approximating a non-existing smoothed classifier. Their experiments demonstrated that the certified (\ell_2)-robustness could be dramatically improved with the proposed regularization, achieving better or comparable results to state-of-the-art approaches with significantly less training costs and hyperparameters.
The development of randomized smoothing techniques has opened new avenues for research in adversarial robustness. By providing a scalable and model-agnostic method for certifying robustness, randomized smoothing addresses some of the key challenges in the field, such as the scalability of adversarial training and the difficulty of certifying robustness for large and expressive neural networks. As the field continues to evolve, further advancements in randomized smoothing are likely to enhance the robustness of machine learning models against adversarial attacks, particularly in complex, multimodal environments.
For more detailed information, you can access the original papers on arXiv:
- «Certified Adversarial Robustness via Randomized Smoothing» by Cohen et al. (2019): arXiv:1902.02918
- «Certified Robustness under Heterogeneous Perturbations via Hybrid Randomized Smoothing» by Delattre et al. (2026): arXiv:2605.12876
- «Consistency Regularization for Certified Robustness of Smoothed Classifiers» by Jeong and Shin (2021): arXiv:2006.04062He buscado información sobre la sesión y el ponente. No localicé una grabación o transcripción pública de esa closing fireside chat concreta, pero sí documentación abundante sobre su anuncio, la trayectoria de Zico Kolter y sus tesis sobre seguridad de IA. A partir de esa base, elaboro el artículo de reseña: